Why in News?
The Hindu examined the effort to make artificial intelligence work across India’s linguistic diversity, drawing attention to the gap between globally dominant language models and the speech, scripts, dialects and public-service needs found in India.
- India’s public language-technology architecture includes BHASHINI, the National Language Translation Mission launched during Digital India Week in July 2022 and implemented through the Digital India BHASHINI Division under Digital India Corporation, MeitY.
- Official MeitY documents describe a wider language stack than translation alone: automatic speech recognition, machine translation, text-to-speech, natural-language understanding, optical character recognition, transliteration and language detection.
- BHASHINI is designed as a national public digital platform for languages, intended to support government agencies, states, startups and other contributors in building Indian-language products and services.
- The IndiaAI Mission complements this work through pillars for compute, datasets, foundation models, application development, skills, startup financing, and safe and trusted AI.
- The policy question is no longer simply whether a model can produce an Indian-language sentence. It is whether the system performs reliably across dialects, code-mixed speech, public-service vocabulary, low-quality audio and high-stakes citizen interactions.
- A service available only in English or a dominant regional language can reproduce the linguistic digital divide even when connectivity and devices improve.
- Language AI can lower the literacy and interface burden by supporting voice, translation, reading assistance and multilingual search, but a wrong translation in health, welfare or grievance redress can also deny an entitlement.
- Low-resource languages face a structural disadvantage because clean, representative and legally usable text and speech datasets are harder to assemble than web-scale English data.
UPSC Relevance
Prelims Relevance
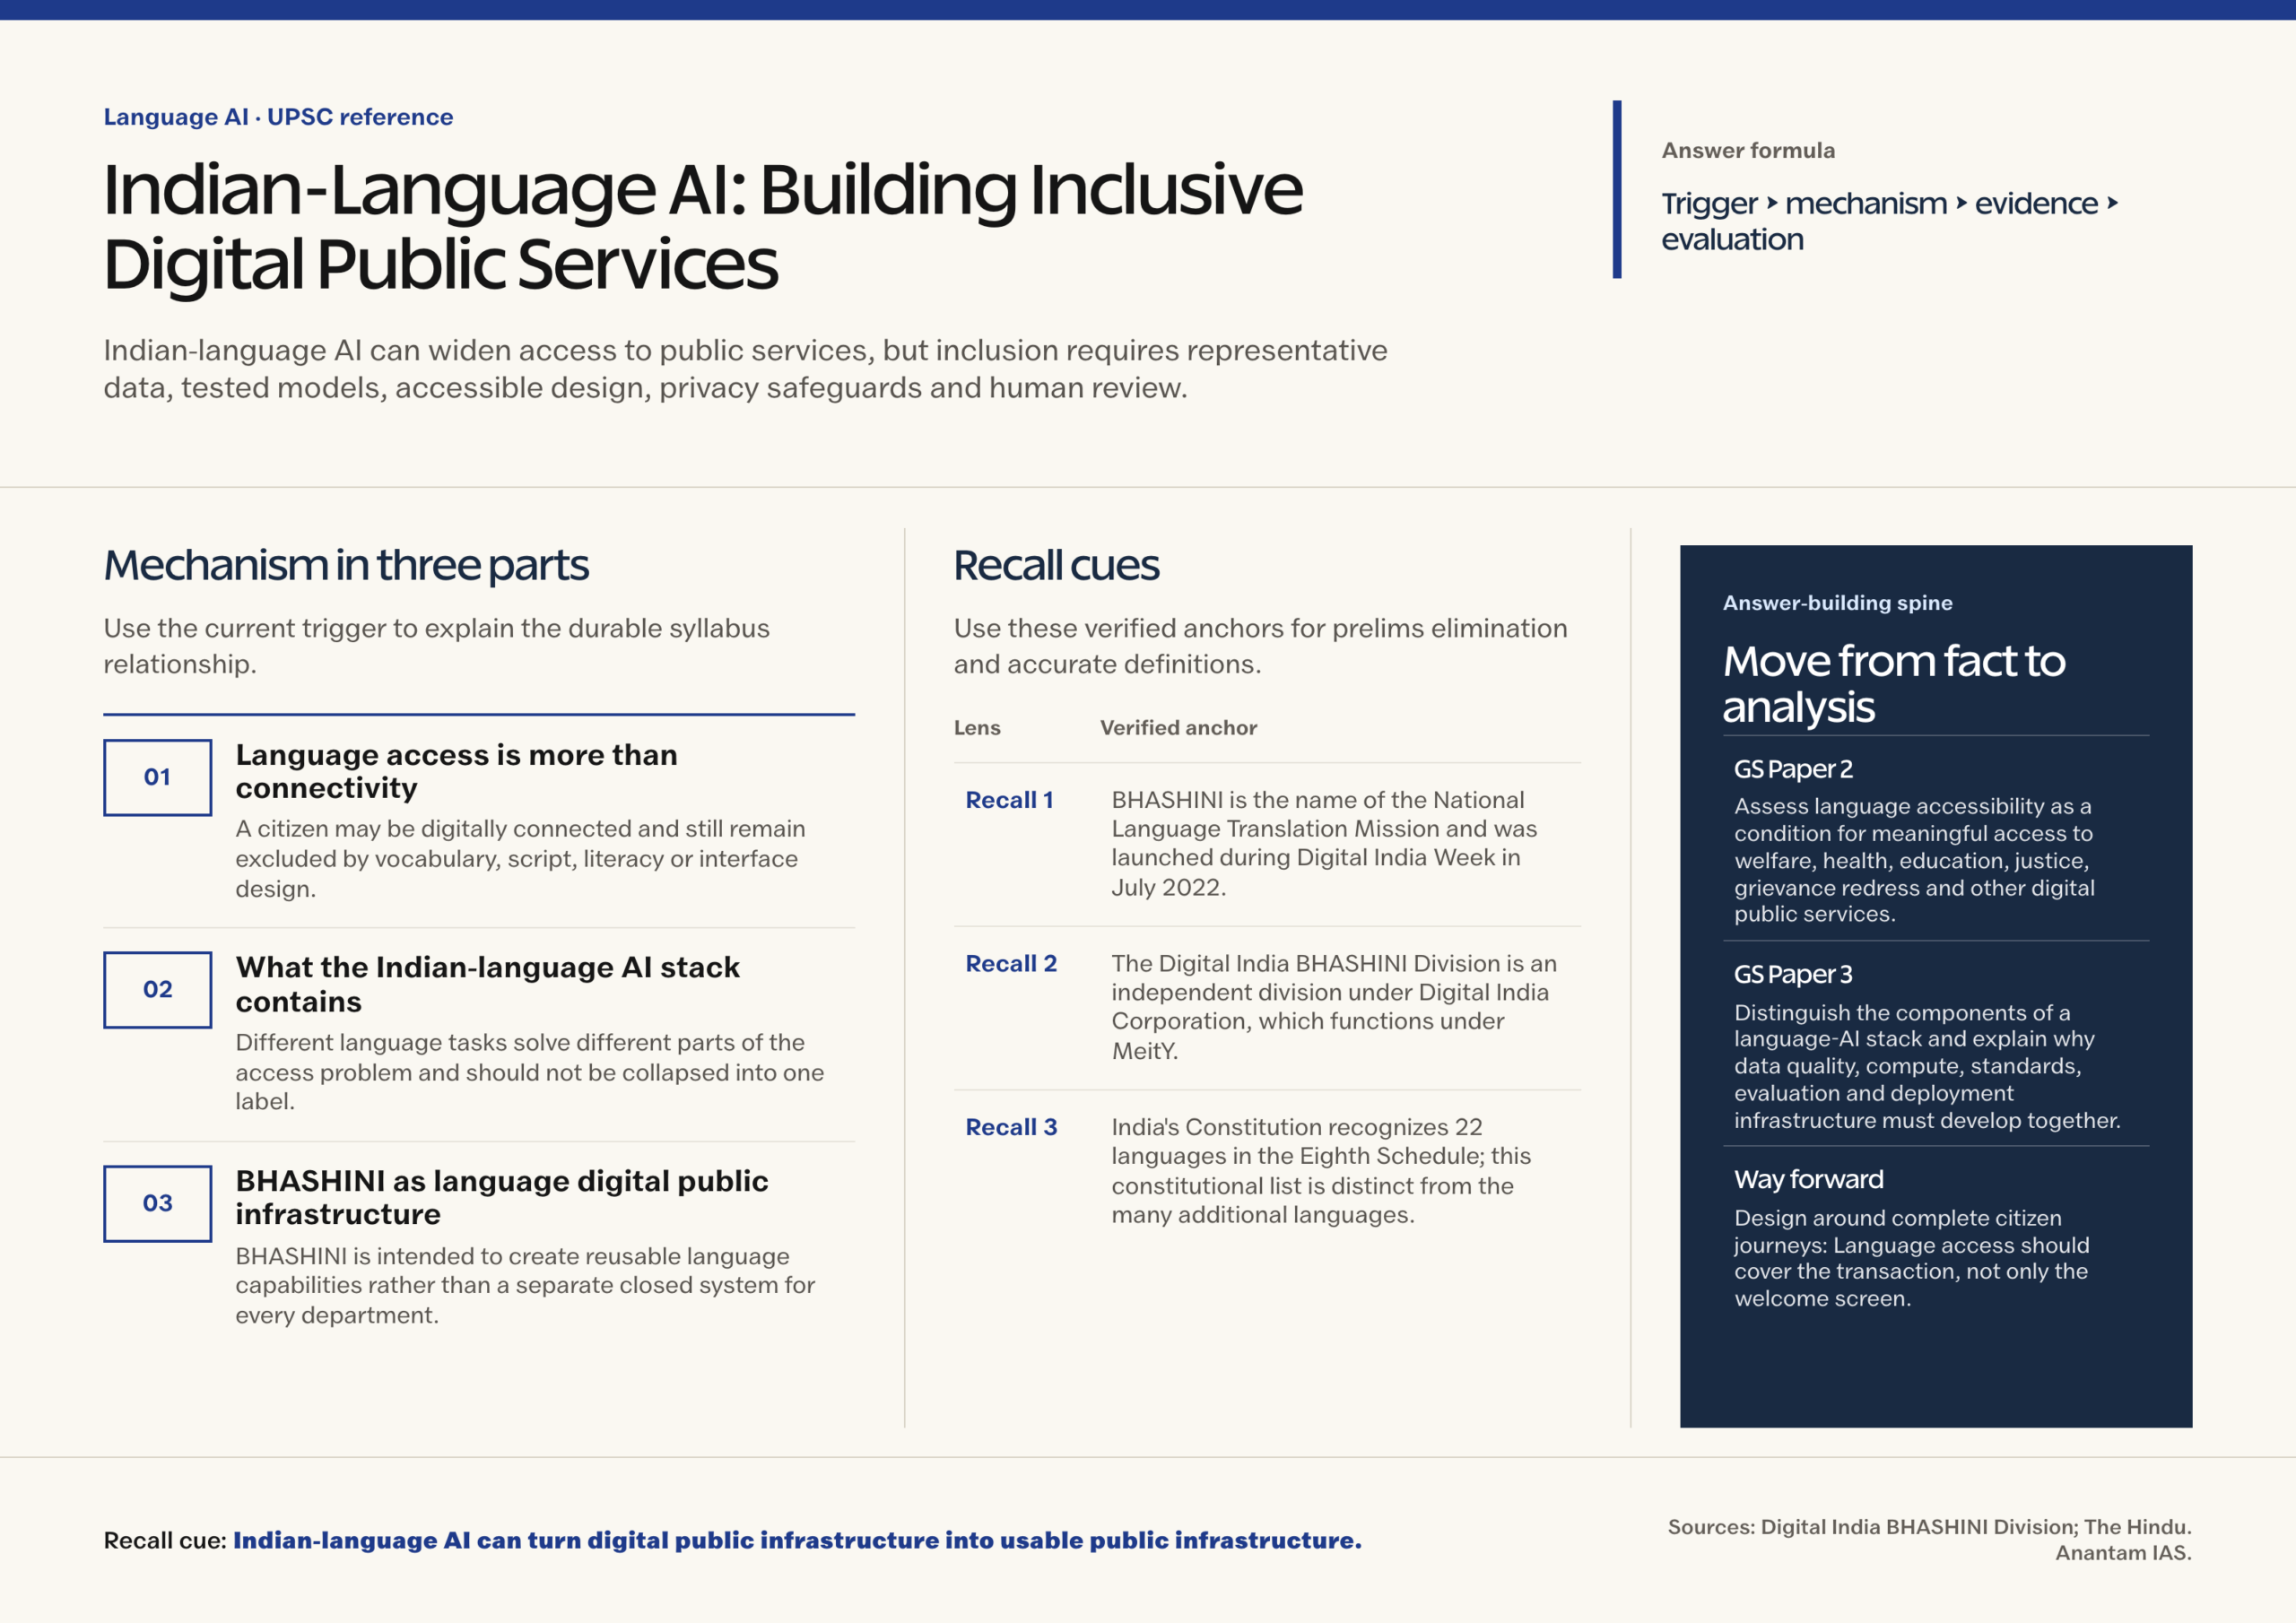
- BHASHINI is the name of the National Language Translation Mission and was launched during Digital India Week in July 2022.
- The Digital India BHASHINI Division is an independent division under Digital India Corporation, which functions under MeitY.
- India’s Constitution recognizes 22 languages in the Eighth Schedule; this constitutional list is distinct from the many additional languages, dialects and speech varieties used across the country.
- Automatic Speech Recognition converts speech into text, while Text-to-Speech converts written text into spoken audio.
- Machine Translation maps content from a source language to a target language; transliteration represents sounds or words in another script without necessarily translating their meaning.
- Optical Character Recognition extracts machine-readable text from images or scanned documents and must be trained and evaluated for the relevant scripts and document conditions.
Mains Relevance
GS Paper 2
- Assess language accessibility as a condition for meaningful access to welfare, health, education, justice, grievance redress and other digital public services.
- Examine the federal and institutional design needed to include state languages, dialect communities and domain experts in public language infrastructure.
GS Paper 3
- Distinguish the components of a language-AI stack and explain why data quality, compute, standards, evaluation and deployment infrastructure must develop together.
- Analyse bias and safety risks arising from low-resource data, code-mixed speech, dialect variation, domain shift and generative-model hallucination.
Essay
- Digital inclusion begins when the state can listen and respond in the language a citizen actually uses.
Background and Context
Language access is more than connectivity
A citizen may be digitally connected and still remain excluded by vocabulary, script, literacy or interface design.
- Public portals often assume that users can read formal administrative language, navigate menus and type accurately. These assumptions disadvantage users who are more comfortable with spoken, regional or code-mixed language.
- Language barriers can affect discovery of a scheme, completion of an application, understanding of eligibility, submission of a grievance and comprehension of the final decision. Translation at only the landing page leaves the core transaction inaccessible.
- Voice interfaces can reduce typing and literacy barriers, but they must work in noisy settings, on low-cost devices and with varied accents. A system that succeeds only with studio-quality speech does not establish practical inclusion.
- Accessibility also overlaps with disability. Text-to-speech may help users with visual impairments, while captions and accurate speech-to-text may help users with hearing-related access needs, subject to the interface and individual context.
- The correct outcome measure is successful completion with informed understanding, not merely the number of languages listed in a menu.
What the Indian-language AI stack contains
Different language tasks solve different parts of the access problem and should not be collapsed into one label.
- Automatic Speech Recognition converts a user’s spoken input into text. It must handle accent, dialect, code-switching, background noise, names and public-service terminology.
- Machine Translation transfers meaning between languages. It requires attention to context, grammar, terminology and ambiguity, especially where a literal translation changes an administrative or legal meaning.
- Text-to-Speech reads text aloud. Natural pronunciation matters, but public-service use also requires correct reading of names, numbers, dates, abbreviations and warnings.
- OCR and transliteration address separate needs. OCR reads text from images or scanned documents; transliteration changes script representation while preserving the sound or form of a word, rather than translating its meaning.
- Natural-language understanding can classify intent or extract entities, while a multilingual foundation model or large language model can answer, summarise or generate text. Generative flexibility must not be mistaken for verified administrative authority.
BHASHINI as language digital public infrastructure
BHASHINI is intended to create reusable language capabilities rather than a separate closed system for every department.
- The official mission vision is to use natural-language technologies to cross language barriers and advance digital inclusion and digital empowerment.
- MeitY describes BHASHINI as a national public digital platform supporting translation among Indian languages and English and enabling an ecosystem of government agencies, states, startups, researchers and citizens.
- Its stated technology scope includes speech-to-speech translation, ASR, machine translation, text-to-speech, natural-language understanding, OCR, transliteration, language detection, data resources, models and benchmarking tools.
- Official documents identify high-use applications such as GeM, eSanjeevani, CPGRAMS, UMANG and UPI123Pay as areas for language interfaces. Each has a different risk profile, so integration must be tested in the actual domain.
- BhashaDaan adds a participatory data route by inviting people to contribute or validate voice, transcription, translation and labelled-image inputs for Indian languages.
Why translation alone is insufficient
A translated interface does not automatically produce a trustworthy multilingual public service.
- Translation usually transforms a defined source text into a target language. A conversational model may instead infer intent, retrieve information, summarise rules and generate a new answer. These are distinct operations with distinct failure modes.
- A fluent answer may still be factually wrong. In a welfare or health interaction, hallucination can convert a helpful interface into an unreliable decision channel.
- Government terminology may have no stable everyday equivalent, and the same word may carry different meanings across regions or domains. Curated glossaries and domain-specific review are needed alongside general models.
- Code-mixing is common in ordinary speech. A user may combine an Indian language with English terms, use a local pronunciation or switch scripts. Evaluation based only on formal written sentences will miss these conditions.
- Language output should be separated from the authoritative decision source. The system should retrieve eligibility, status and entitlements from verified records and show the citizen where the answer came from.
Way Forward
Design around complete citizen journeys
- Map each service from discovery to application, payment, status tracking, notice, grievance and appeal, then test whether the user can complete every step in the chosen language.
- Offer voice, text and assisted channels together so users can switch when speech recognition, literacy, connectivity or privacy conditions make one mode unsuitable.
- Fund language communities, universities and public institutions to create documented datasets across dialects, scripts, domains and real acoustic conditions, with clear consent and licences.
- Maintain dataset cards and model cards covering provenance, intended use, excluded uses, known gaps, version history and disaggregated evaluation.
Conclusion
- Indian-language AI can turn digital public infrastructure into usable public infrastructure .
- The governing principle should be simple: language technology must expand a citizen’s ability to understand, act and appeal.
UPSC Practice Questions
Prelims MCQ 1
With reference to BHASHINI, consider the following statements:
- It is the name given to the National Language Translation Mission.
- Its technology scope includes speech recognition, machine translation, text-to-speech and optical character recognition.
- It is implemented by the Election Commission of India.
How many of the above statements are correct?
(a) Only one (b) Only two (c) All three (d) None
Answer: (b) Only two
Explanation:
Statements 1 and 2 are correct. Statement 3 is incorrect: BHASHINI is implemented through the Digital India BHASHINI Division under Digital India Corporation, MeitY, not by the Election Commission of India.
Prelims MCQ 2
Which one of the following correctly distinguishes transliteration from machine translation?
(a) Transliteration changes script representation while broadly preserving the word’s sound or form; translation transfers meaning into another language (b) Transliteration converts speech to text; translation converts text to speech (c) Transliteration extracts text from scanned images; translation identifies the language of a document (d) Transliteration generates an administrative decision; translation verifies that decision against official records
Answer: (a) Transliteration changes script representation while broadly preserving the word's sound or form; translation transfers meaning into another language
Explanation:
Transliteration represents a word in a different script with attention to its sound or written form. Machine translation seeks to express the meaning of source-language content in a target language.
UPSC Mains Questions
- Indian-language AI is not merely a translation problem; it is a question of equal access to the digital state. Discuss with reference to public-service design and social justice.
- Distinguish the major components of a language-AI stack. What technical and institutional safeguards are needed before deploying it in high-stakes public services?
Sources: Digital India BHASHINI Division and The Hindu.
Frequently Asked Questions
What is BHASHINI?
BHASHINI is the name of India’s National Language Translation Mission. Launched during Digital India Week in July 2022, it is implemented through the Digital India BHASHINI Division under Digital India Corporation, MeitY, and seeks to build a national public digital.
Is Indian-language AI the same as machine translation?
No. Machine translation transfers meaning between languages. A language-AI system may also use speech recognition, text-to-speech, OCR, transliteration, intent detection, retrieval and generative models. Each component has different data needs and failure modes, and the complete service must be tested.
Why are low-resource languages difficult for AI systems?
They often have less digitised text, labelled speech, parallel translation data and domain-specific material. Available data may overrepresent formal writing or a few accents. Model quality also depends on documentation, licensing, annotation, evaluation and community review, not only the size.
How can language AI improve digital public services?
It can support voice queries, multilingual search, translated instructions, reading assistance, form completion and grievance access. The gain is meaningful only when citizens can complete the entire transaction, understand the outcome, correct recognition errors and reach a human when the.
What is the biggest risk of using generative AI in welfare or health services?
A fluent response may be inaccurate, unsupported or inconsistent with the authoritative rule. In high-stakes services, the system should retrieve from verified sources, disclose its automated role, preserve a traceable source, apply confidence thresholds and defer to trained human assistance.
Tell Google you want more of this.
Add Anantam IAS as a preferred sourceOne tap, and this site shows up more often in your own Top Stories, AI Overviews and AI Mode. Remove it any time.